

zoom_in View Full Benchmark
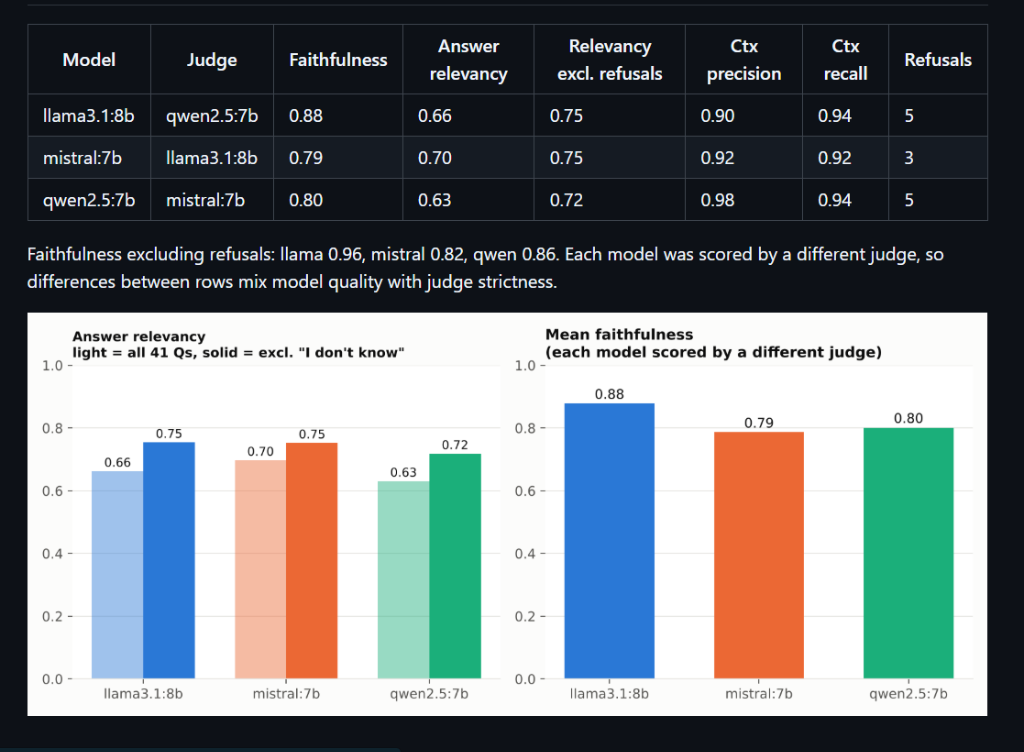
RAGAS Evaluation across 41 test questions. Compares Faithfulness (Llama: 0.88, Mistral: 0.79, Qwen: 0.80), Answer Relevancy (0.63–0.70 raw, 0.72–0.75 excluding refusals), and Refusals (Llama: 5, Mistral: 3, Qwen: 5). Differences between rows mix model generation quality with judge strictness.
3 Local Models
Llama, Mistral, Qwen
4 RAGAS Metrics
Faithfulness & Relevancy
5.1s – 6.4s
Median Inference Latency
Offline RAG with Evaluation Benchmark
An offline Retrieval-Augmented Generation (RAG) system with an automated evaluation pipeline for comparing different language models. The project uses RAGAS to evaluate generated answers across Faithfulness, Answer Relevancy, Context Precision, and Context Recall, helping analyze answer quality and retrieval performance.
Python
FastAPI
Ollama
FAISS
RAGAS
LangChain